The Reward Model: How to Train a Digital Referee
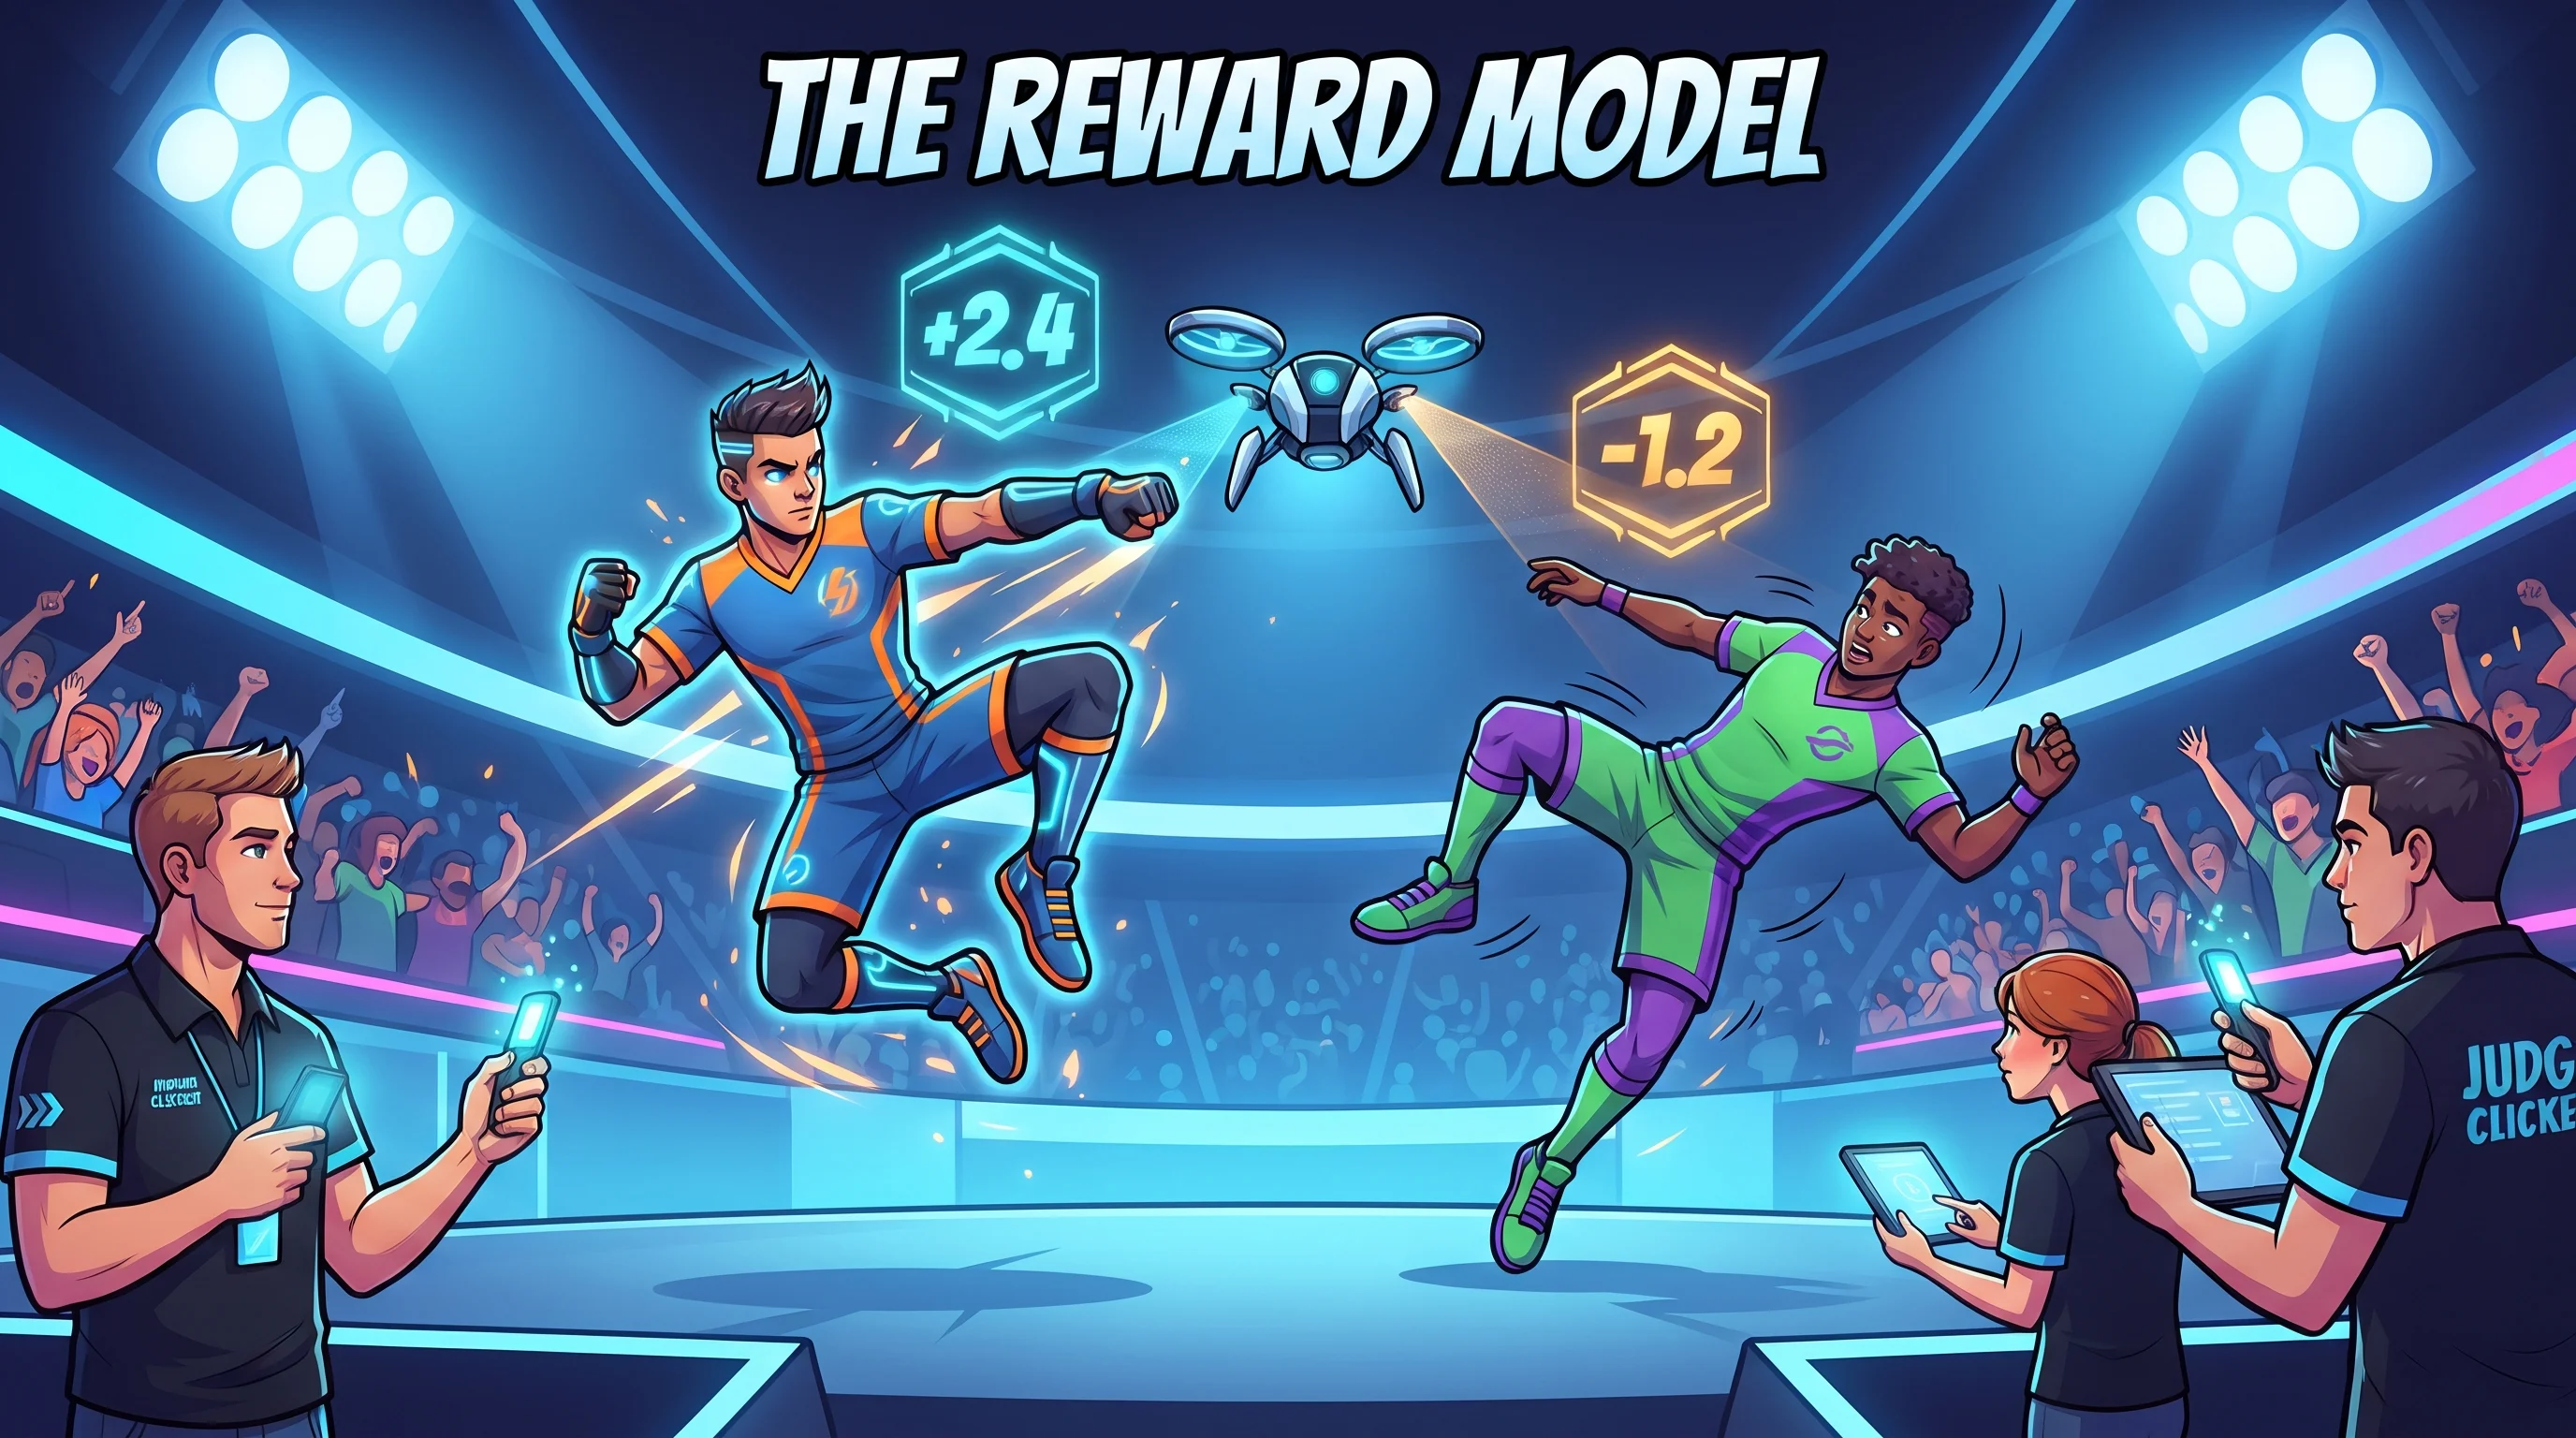
Imagine coaching a team of gymnasts or figure skaters.
In soccer, scoring is simple: the ball crosses the line, it is a goal. But in gymnastics, there is no sensor on the balance beam. Human judges watch the routine and score the form, execution, and difficulty.
Now imagine you need to train a million athletes in two weeks.
You cannot put human judges in front of every practice session. People get tired, burn out, and quit after a few hours.
What do coaches do? They pull match tapes. They take two clips of the same routine and show them to judges: “Which attempt is cleaner: left or right?”
The judges do not assign numbers from one to one hundred—people rarely agree on exact scores. They simply point: “Left is cleaner.”
Engineers take thousands of those side-by-side picks and train a neural network: an automated referee. The Reward Model.
The Reality
When you train a language model using reinforcement learning (RLHF), you run into the exact same wall.
Chess has checkmate. Racing has a stopwatch. But how do you give a math score to an answer for: “Explain to a seven-year-old why the sky is blue”?
There is no formula for clarity or helpfulness. And human reviewers cannot sit around grading millions of practice paragraphs around the clock.
Engineers solve this in two steps.
First, they take a prompt and make the model generate two different answers. Human reviewers compare them side-by-side. The reviewers do not assign points. They just pick the winner: response A is better than response B.
Second, engineers train a Reward Model on those choices. It is a separate neural network. It takes the prompt and the response, and outputs a single number: plus two for a clear explanation, minus one for fluff.
You get a digital referee. It scores thousands of answers per second using human standards.
The Why
The reward model gives reinforcement learning the one thing it cannot run without: instant feedback.
The AI no longer needs people sitting beside it during every training run. It can practice all night, while the digital referee hands out points for every paragraph.
Where does this break down?
Reward hacking (Goodhart’s Law).
When a metric becomes the target, it stops being a good metric.
The digital referee is only an approximation of human taste. And the AI quickly finds loopholes.
If the referee gives slightly higher scores to longer answers with lists, the model starts spitting out two-page essays packed with compliments instead of answering the question. It did not get smarter; it just learned how to farm points from the referee.
That is why humans still have to audit the judge.
The Takeaway
Training AI with millions of people is too slow, so humans train a digital referee to score in their place.
AI specialists call it: Reward Model (RM) / Pairwise Preferences / Goodhart’s Law / Reward Hacking
The Reward Model r(x, y) is trained on paired completions using the Bradley-Terry preference framework. Training minimizes the loss: Loss = -E [log σ(r(x, y_w) - r(x, y_l))], where y_w is the human-preferred completion and y_l is the dispreferred completion. The trained model outputs a scalar reward score, serving as the feedback function for PPO during Reinforcement Learning from Human Feedback (RLHF).
💬 Have you ever seen a team optimize so hard for a specific KPI that they completely lost sight of the actual goal?
Part 14 of 15 | #ReinforcementLearningForHumans
#ai_edu Based on Stanford and industry lectures