Sherlock vs The Accountant: Why Pure Vector Search Loses to Hybrid Search
An automated compliance pipeline searches ten thousand supplier specification sheets to audit an industrial dessert glaze against European V-Label standards: “Retrieve supplier technical datasheets containing food coloring code E120 or glazing agent E904.”
The vector search engine returns its top match with a 0.92 cosine similarity score:
“Organic Strawberry Glaze: A vibrant crimson botanical extract providing natural red hue for plant-based confectionery and vegan pastry applications.”
The vector database understood the general conceptual vibe of “crimson coloring for vegan pastries.” But buried on page 42 of search results was the actual document the auditor needed—a two-line supplier certificate declaring: “Product contains Food Color E120 (Carmine / Cochineal extract from crushed insects).”
By relying purely on semantic vector embeddings, the system missed the exact alphanumeric string that legally invalidates the product’s vegan certification.
Welcome to the blind spot of dense vector search.
The Detective vs The Ledger Clerk
To understand why modern search pipelines combine two fundamentally different search engines, look at how humans solve investigations.
Imagine a burglary at a historic trading warehouse. You have two distinct investigators on the scene:
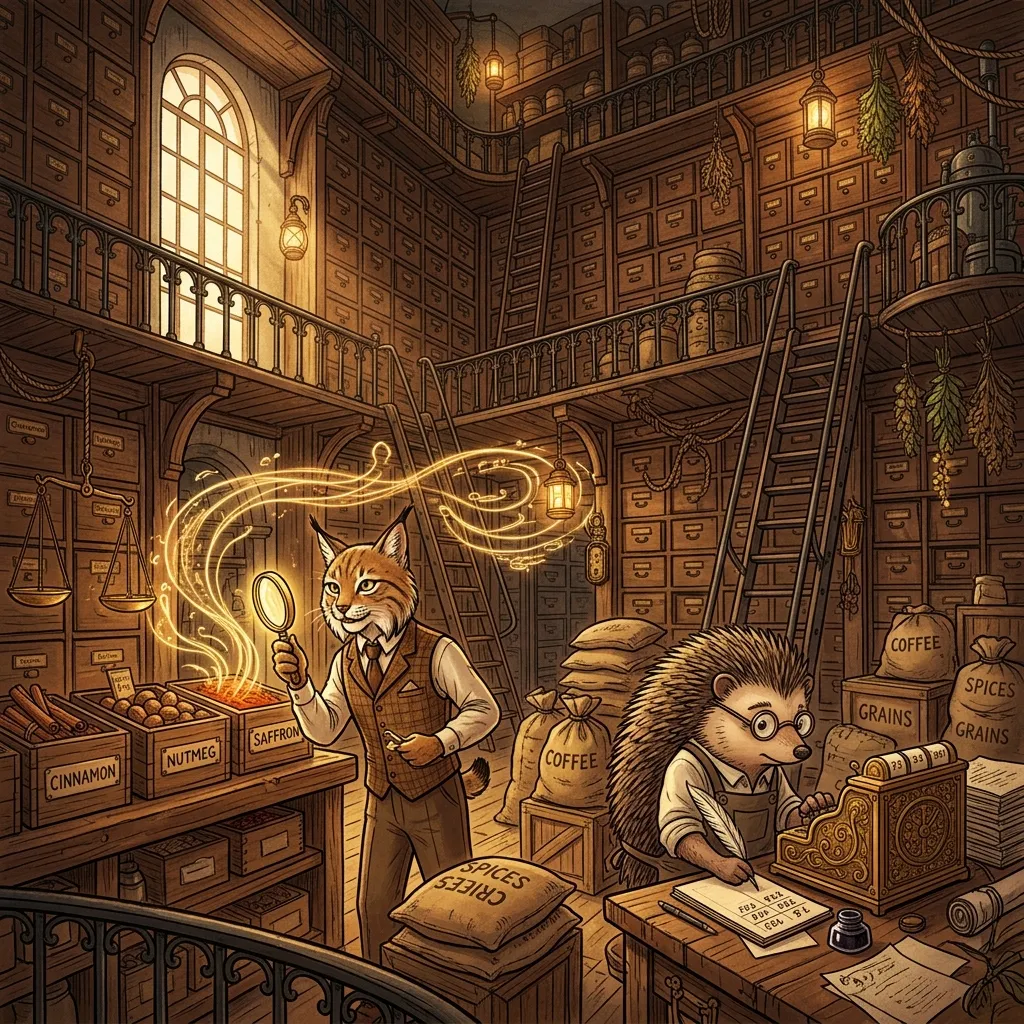
Detective Sherlock works through intuition and atmospheric clues. He smells tobacco smoke, observes scuff marks on a crate, and deduces that the intruder was nervous, hurried, and entered from the river dock. Sherlock is brilliant at connecting abstract concepts, but he gets bored reading shipping manifests.
The Accountant sits on a crate in the back room with round spectacles and a pencil. He possesses zero romantic intuition. He does not care about mood, vibes, or atmospheric deductions. He cares about one thing: checking whether stamped serial code #E120-B on a wooden crate matches the customs registry.
Vector search is Sherlock: exceptional at recognizing that “dairy-free oat drink” is semantically identical to “plant-based cereal beverage,” but completely blind to exact alphanumeric part numbers.
BM25 is the Accountant: utterly incapable of understanding poetry, synonyms, or conceptual context, but relentlessly fast at locating the exact characters E120 or CAS 56-81-5 across a million documents.
Where the analogy breaks down: in real life, a detective and a clerk can discuss findings over coffee. In computer science, they evaluate reality on mathematically incompatible scales. Vector search outputs continuous cosine similarity scores from 0.0 to 1.0, while BM25 outputs unbounded statistical term-frequency scores that can range from 0 to 45.8. You cannot simply add them together.
How the Accountant Calculates: The BM25 Algorithm
Before exploring how to combine them, look at why BM25 (Best Matching 25) remains the gold standard of lexical retrieval after decades of production use:
BM25 Score(D, Q) = sum( IDF(q_i) · [ (TF · (k1 + 1)) / (TF + k1 · (1 - b + b · (|D| / avgdl))) ] )BM25 evaluates candidate documents through three disciplined principles:
- Term Frequency (TF) with Saturation: The more times a search term appears in a document, the higher the score. But unlike naive keyword counting, BM25 uses an asymptotic saturation curve. Mentioning the code
E120ten times is not ten times more valuable than mentioning it once; the curve flattens out. - Inverse Document Frequency (IDF): If the word “ingredient” appears in every single document across your database, its IDF weight drops to zero. But if the alphanumeric code
"E120"appears in only two supplier certificates across the entire archive, its statistical weight becomes massive. - Document Length Penalty: Finding an exact keyword match in a concise, three-paragraph Certificate of Analysis carries significantly higher statistical relevance than finding that same keyword mentioned once in an eight-hundred-page company catalog.
The Mathematical Dilemma: Adding Apples to Oranges
When an engineering pipeline runs both retrievers simultaneously, it ends up with two completely disjointed candidate scoreboards:
- Vector Search (Dense): Generates scores between
0.00and1.00. - BM25 (Sparse): Generates scores between
0.00and45.80, with unpredictable spikes depending on document length and keyword rarity.
Attempting to compute a combined score through naive addition:
Score = Vector_Cosine + BM25_Score # Flawed: BM25 completely drowns the vectorThe statistical spikes of BM25 will overpower the fractional variations of cosine similarity. A noisy document with four accidental keyword hits will easily defeat a semantically perfect document with a 0.95 cosine score.
The Solution: Reciprocal Rank Fusion (RRF)
Modern hybrid search solves this dilemma through Reciprocal Rank Fusion (RRF).
Instead of trusting unstable absolute score magnitudes, RRF discards the raw scores entirely and evaluates only the ordinal rank positions of each document across the two lists:
RRF_Score(d) = sum_over_retrievers( 1 / (k + rank_m(d)) )- The Rank Factor
rank_m(d): The 1-based integer position of documentdin retrieverm(1st place, 2nd place, 3rd place). - The Constant
k: Set to60following the empirical standard established by researchers Bell and Cormack. It acts as a smoothing factor, ensuring that finishing 1st in only one search engine does not automatically beat a document that finished 2nd in both.
How the Math Resolves Candidate Documents
Look at what happens to three competing supplier chunks during retrieval:
- Chunk A (Validated by Both): Takes 1st place in BM25 (exact
E120code match) and 1st place in Vector search (high semantic relevance):Score = 1/(60 + 1) + 1/(60 + 1) = 1/61 + 1/61 ≈ 0.0328(Clear Winner!) - Chunk B (Vector-Only Match): Takes 2nd place in Vector search, but was not retrieved by BM25:
Score = 1/(60 + 2) + 0 = 1/62 ≈ 0.0161 - Chunk C (Keyword-Only Match): Takes 1st place in BM25, but was unranked by Vector search:
Score = 1/(60 + 1) + 0 = 1/61 ≈ 0.0164
Chunk A rises to the very top because it earns corroboration from both the intuitive semantic detective and the meticulous keyword clerk.
Implementing Hybrid Retrieval in Code
In production compliance architectures, hybrid search pipelines execute both queries concurrently and fuse candidate lists before passing documents downstream:
# Production pattern: Concurrent BM25 + Dense retrieval with RRF fusion
def hybrid_compliance_search(query_text: str, top_k: int = 50, k_constant: int = 60):
    # 1. Fetch ranked candidates from both specialized engines
    bm25_ranked_ids = bm25_index.search(query_text, limit=top_k)
    dense_ranked_ids = vector_index.search(query_text, limit=top_k)

    rrf_scores = {}

    # 2. Accumulate reciprocal rank weights from lexical search
    for rank, doc_id in enumerate(bm25_ranked_ids, start=1):
        rrf_scores[doc_id] = rrf_scores.get(doc_id, 0.0) + (1.0 / (k_constant + rank))

    # 3. Accumulate reciprocal rank weights from dense vector search
    for rank, doc_id in enumerate(dense_ranked_ids, start=1):
        rrf_scores[doc_id] = rrf_scores.get(doc_id, 0.0) + (1.0 / (k_constant + rank))

    # 4. Sort documents strictly by fused reciprocal score
    fused_candidates = sorted(rrf_scores.items(), key=lambda x: x[1], reverse=True)
    return [doc_id for doc_id, score in fused_candidates[:top_k]]
When building industrial RAG for technical compliance, neither intuition nor record-keeping is sufficient on its own. Pairing dense embeddings with BM25 ensures your system understands high-level intent without losing the exact alphanumeric codes that keep your product legally compliant.
Next Monday, in Chapter 6, we explore The Two-Level Interrogation (Cross-Encoder Reranking): why feeding the top-50 fused candidates directly to an LLM still creates dangerous hallucinations, and how a cross-encoder performs token-by-token forensic analysis to surface the purest evidence.
Have you ever encountered a search query where vector embeddings completely ignored an essential product ID or SKU in favor of a superficially similar description?